Nistro AI Inference
Run any open-weight model from Hugging Face on GPUs with cost-effective pricing, behind an OpenAI-compatible endpoint.
Paste a model id, pick a location, and Nistro AI finds the most cost-effective GPU, deploys the model and gives you an endpoint and API key. Your existing OpenAI code works by changing the base URL and key.
Quick start#
- In the console, open Inference Deployments and select Create.
- Choose the On-Demand plan, enter a Hugging Face model id such as
google/gemma-4-26B-A4Band pick a Location. - Select Recommend hardware, then View pricing, then Deploy.
- When the deployment is ready, open its Call the API tab, set your key and send a request:
export NISTRO_API_KEY='<api-key>'
curl https://<endpoint>/openai/v1/chat/completions \
  -H "Authorization: Bearer $NISTRO_API_KEY" \
  -H "Content-Type: application/json" \
-d '{"model":"<model>","messages":[{"role":"user","content":"Hello"}]}'Plans#
| On-Demand | Scale | Enterprise | |
|---|---|---|---|
| Hardware | A fractional or single GPU, matched to your model | Dedicated GPU machines, including multi-GPU | Dedicated GPU machines in your own cloud account |
| Placement | A location: US, EU, Asia or Any | The location, cloud, region and instance type you choose | Your cloud account, region and instance type |
| Scaling | Scales to zero when idle and back up on the next request | Multiple replicas, scaled on demand | Multiple replicas in your account |
| Quantization and context length | Yes | Yes | Yes |
| Private and gated Hugging Face models | Yes | Yes | Yes |
| High availability controls | — | Yes | Yes |
| Custom LoRA adapters | — | — | Yes |
| Platform support | Basic | SLA-backed | Enterprise-grade |
You pay for the GPUs you run, not per token. Prices are on the pricing page.
Enterprise runs Nistro AI Inference inside your own AWS, Google Cloud, Azure or Nebius account, so your data and inference traffic stay in your perimeter and run on your existing cloud commitments. Connect the account under Cloud Accounts, then pick the Enterprise plan when you create a deployment. See Cloud accounts.
Create a deployment#
Open Inference Deployments and select Create, then pick a plan.
Choose a model#
Enter a Hugging Face model id, such as google/gemma-4-26B-A4B, or paste its huggingface.co URL. The console finds the model as you type and shows its architecture, data type and maximum context length.
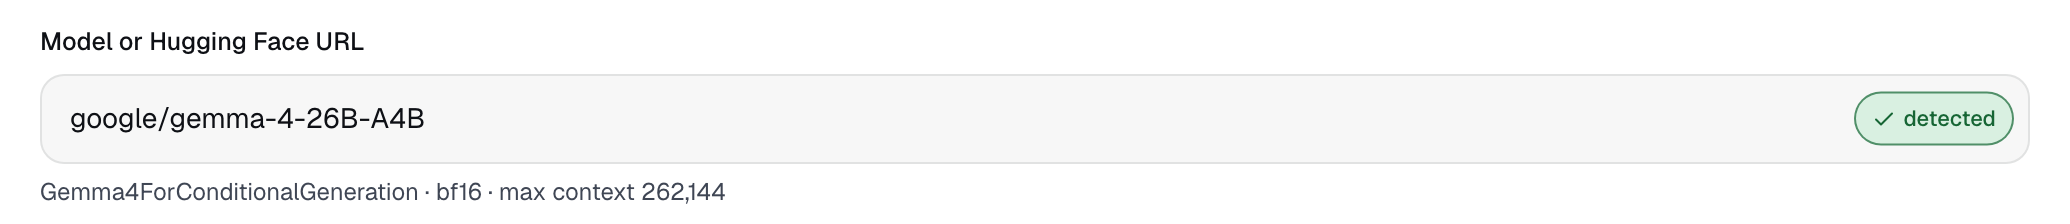
Nistro AI serves models in Safetensors, PyTorch and GGUF formats.
Under Advanced you can also set:
- Quantization: Auto uses what the repository provides, or pick one of the variants the repository offers.
- Context length: defaults to the model's full context, or set a shorter one.
On-Demand plan#
- Enter the model and choose a Location.
- Select Recommend hardware. Based on your model, context length and location, Nistro AI finds the most cost-effective GPU that meets your requirements.
- Select View pricing, review the deployment, then select Deploy.
Create from your terminal with the Inference On-Demand CLI commands.
Scale plan#
- Enter the model, choose a Location and set the number of Replicas. Each replica runs on its own dedicated GPU machine.
- Optionally pick a GPU type under Advanced, or keep Any.
- Select Recommend hardware, then choose the cloud, region and instance type from the machines that fit your model.
- Select View pricing, review the deployment, then select Deploy.
Create from your terminal with the Inference Scale CLI commands.
Enterprise plan#
- Connect your cloud account first.
- Enter the model, then under Placement choose your Cloud account, the Region and the Instance type.
- Review the deployment, then select Deploy. It runs in your account.
The deployment's page opens and shows its progress.
Call the API#
A ready deployment shows its OpenAI-compatible endpoint on the Overview tab. The Call the API tab shows its API key, labelled API key (NISTRO_API_KEY), and ready-to-copy requests with your endpoint and model filled in.
- The API's base URL is your endpoint followed by
/openai/v1. - Send the key as a Bearer token in the
Authorizationheader. - Use the model name shown in the Call the API examples.
Store the key in an environment variable:
export NISTRO_API_KEY='<api-key>'Chat completions#
curl https://<endpoint>/openai/v1/chat/completions \
  -H "Authorization: Bearer $NISTRO_API_KEY" \
  -H "Content-Type: application/json" \
-d '{"model":"<model>","messages":[{"role":"user","content":"Hello"}]}'Streaming#
curl https://<endpoint>/openai/v1/chat/completions \
  -H "Authorization: Bearer $NISTRO_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{"model":"<model>","messages":[{"role":"user","content":"Hello"}],"stream":true}'
The streaming examples reuse the client from the chat completions example above.
Other endpoints#
List the deployment's models:
curl https://<endpoint>/openai/v1/models \
  -H "Authorization: Bearer $NISTRO_API_KEY"
Text completions:
curl https://<endpoint>/openai/v1/completions \
  -H "Authorization: Bearer $NISTRO_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{"model":"<model>","prompt":"Hello","max_tokens":64}'
Scale to zero#
On-Demand deployments scale to zero when they're idle, so you aren't paying for GPUs you don't use. The Live status card shows Idle, and the deployment scales back up automatically on the next request, showing Scaling up until it's serving.
Scale deployments keep dedicated replicas ready to serve at all times.
Monitoring#
The Overview tab updates live while the deployment runs:
- Live status shows the ready and total replicas, the replica range and when the deployment was last active.
- Live metrics show in-flight and waiting requests, tokens per second, p50 and p95 latency and KV cache usage.
- Charts track throughput, in-flight requests, end-to-end p95 latency and KV cache utilization over time.
Across all your deployments, Alerts flag what needs attention and notify you by email or Slack, the Activity Log records what changed, and Usage shows usage and cost.
Replicas#
On Scale, change the number of replicas from the Replicas card on the Overview tab. The deployment shows updating while the change rolls out.
Delete#
Select the delete icon in the deployment's header, or Delete deployment on the Danger tab, and type delete to confirm. Deleting can't be undone.